Technical SEO Audit Checklist for Modern Web Platforms
Great content cannot rank on broken architecture. Use this engineer-tested technical SEO checklist to eliminate crawl errors, fix indexing, and pass vitals.
Technical SEO Audit Checklist for Modern Web Platforms
Search engine optimization is often treated as a content exercise.
Teams research keywords, write articles, optimize headings, and publish consistently. All of that matters, but great content cannot compensate for a website that search engines struggle to crawl, render, understand, or trust.
If JavaScript delays meaningful content, canonical URLs are inconsistent, important pages are buried deep in the site structure, or server response times remain slow, your content may never get the visibility it deserves.
That is why technical SEO should be treated as part of the engineering process, not something added after a website has already been built.
This technical SEO audit checklist covers the core areas we evaluate when improving a web platform for search visibility, performance, crawlability, and AI-driven discovery.
Technical SEO Audit Checklist
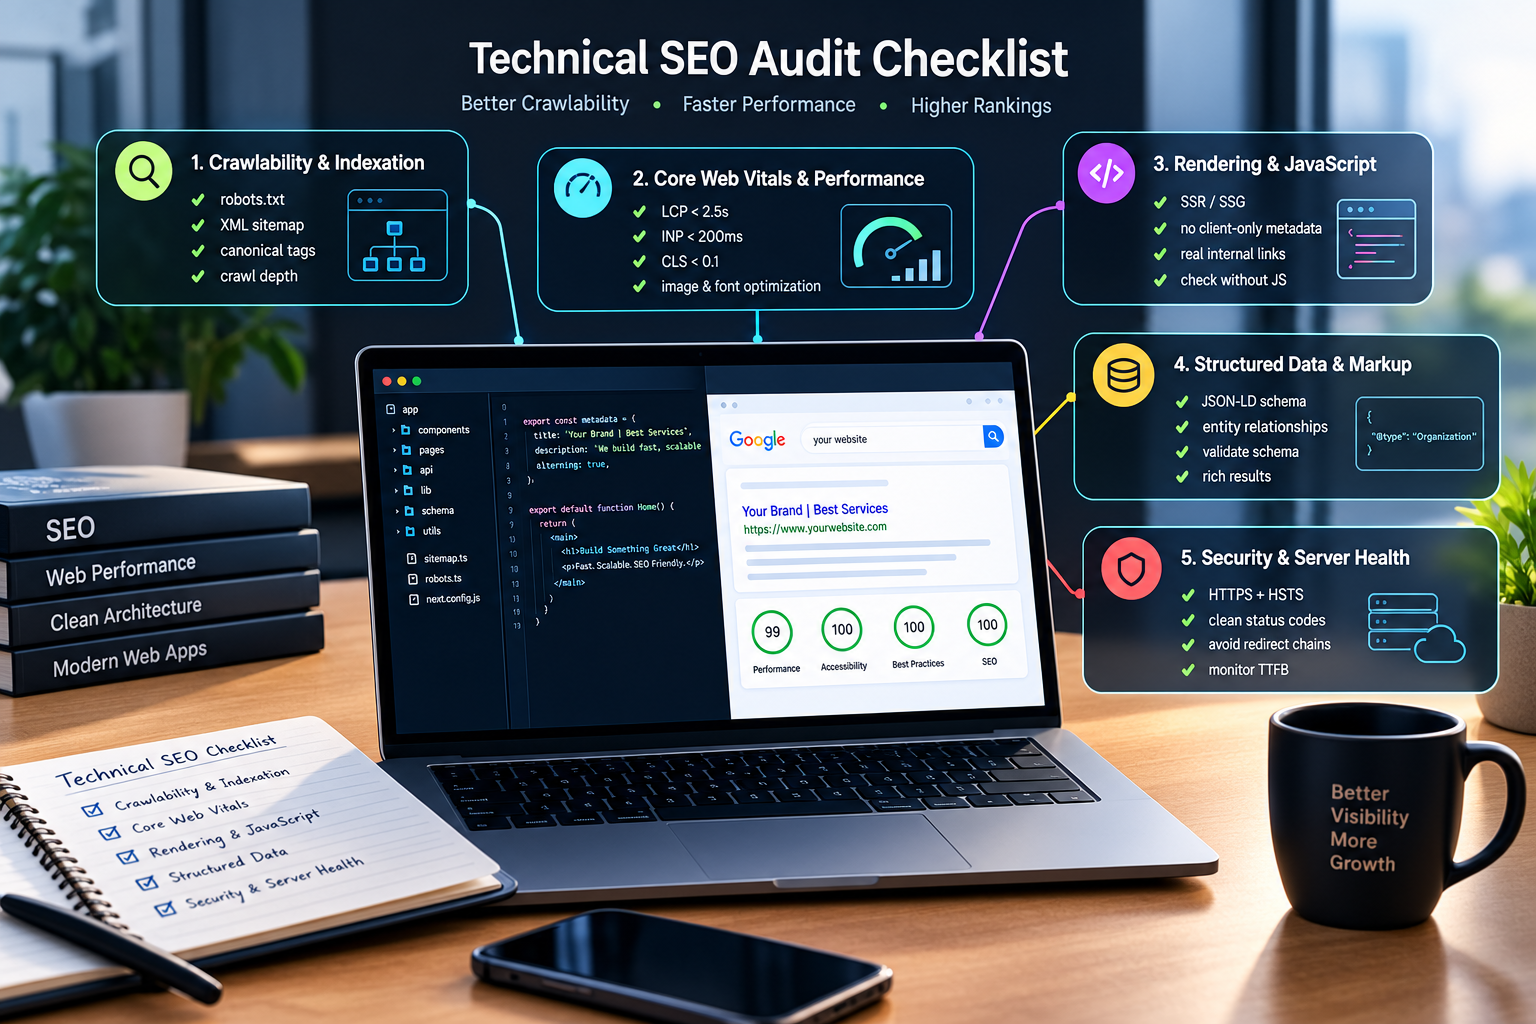
A complete technical SEO audit should examine at least these five areas:
- Crawlability and indexation
- Core Web Vitals and performance
- Rendering and JavaScript
- Semantic markup and structured data
- Security and server health
Let's look at each one.
1. Crawlability and Indexation
Before a page can appear in search results, search engines need to be able to discover, crawl, render, and index it.
Small technical mistakes can prevent important pages from being properly discovered or can cause search engines to waste crawl resources on URLs that should never have been indexed.
Audit Your robots.txt
Your robots.txt file should prevent unnecessary crawling without accidentally blocking resources required to render your website.
Check that important assets such as:
- JavaScript files
- CSS files
- Fonts
- Images
- Public API resources required for rendering
are not unintentionally blocked.
A restrictive robots.txt configuration can create unexpected rendering and indexing problems.
Validate Your XML Sitemap
Your XML sitemap should contain the URLs you actually want search engines to discover and index.
A properly generated sitemap should:
- Include canonical URLs.
- Exclude pages marked
noindex. - Exclude URLs returning
404errors. - Exclude redirected URLs where possible.
- Update automatically when content changes.
- Use the correct HTTPS and URL structure.
Individual sitemap files can contain up to 50,000 URLs or 50 MB of uncompressed data, after which they should be split into multiple sitemap files and referenced through a sitemap index.
For content-heavy websites, programmatically generated sitemaps are generally more reliable than manually maintained files.
Check Canonical URLs
Duplicate URLs can create unnecessary ambiguity for search engines.
For example:
https://example.com/services
https://example.com/services/
http://example.com/services
https://www.example.com/services
If these variations are accessible as separate URLs, your site can end up with inconsistent signals.
Establish one preferred URL structure and enforce it consistently.
For canonical pages, use self-referencing canonical tags where appropriate and redirect non-preferred URL variants using permanent redirects.
Review Crawl Depth
Important pages should not be unnecessarily buried deep within the site's navigation structure.
Your highest-value pages should generally be reachable within a few clicks from important entry points such as the homepage or major category pages.
For example:
Homepage
   │
   ├── Services
   │     ├── Web Development
   │     └── AI Automation
   │
   └── Resources
         ├── Blog
         └── Guides
A clear hierarchy makes it easier for both users and crawlers to discover important content.
2. Core Web Vitals and Real-World Performance
A website can score well in a local Lighthouse test and still feel slow to real users.
Google's Core Web Vitals use field data to evaluate important aspects of real-world page experience.
The three primary metrics are:
| Metric | Good Target | What It Measures | Common Fixes |
|---|---|---|---|
| LCP | < 2.5s | Loading performance | Optimize hero assets, caching, CDN delivery, critical CSS |
| INP | < 200ms | Interaction responsiveness | Reduce JavaScript work, break up long tasks |
| CLS | < 0.1 | Visual stability | Reserve space for images, embeds, and dynamic content |
Passing laboratory tests is useful, but real-user performance should remain the ultimate goal.
Optimize Largest Contentful Paint
Large hero images, slow fonts, server delays, and excessive JavaScript can all affect LCP.
Common improvements include:
- Preloading important hero assets.
- Compressing images.
- Using modern image formats.
- Serving assets through a CDN.
- Caching public pages.
- Reducing render-blocking resources.
- Keeping critical CSS lightweight.
The goal is simple:
Deliver the most important visible content as quickly as possible.
Improve Interaction to Next Paint
A page can load quickly and still feel sluggish when users interact with it.
Large JavaScript bundles and long-running main-thread tasks can delay interaction.
Reduce unnecessary client-side work by:
- Splitting large JavaScript bundles.
- Removing unused dependencies.
- Deferring non-critical scripts.
- Breaking long-running tasks into smaller units.
- Moving suitable computational work away from the main thread.
Prevent Cumulative Layout Shift
Nothing feels less polished than clicking a button only for the page to move underneath your cursor.
Reserve space for content that loads dynamically by defining dimensions for:
- Images
- Videos
- Advertisements
- Embeds
- Dynamic banners
- Other asynchronously loaded components
For images, explicit width and height attributes or an appropriate aspect-ratio container can prevent unexpected layout movement.
Optimize Images and Fonts
Large assets can significantly increase page weight, particularly on mobile connections.
Use:
- AVIF or WebP where appropriate.
- Responsive
srcsetimages. - Proper image dimensions.
- Lazy loading for below-the-fold media.
- CDN-based image optimization.
For fonts, consider font-display: swap, variable fonts, and appropriate metric overrides to reduce invisible text and layout shifts.
3. Client-Side Rendering vs. Static HTML
JavaScript-heavy applications can create additional challenges for search engines.
Modern search engines are capable of rendering JavaScript, but relying heavily on client-side rendering can still introduce unnecessary complexity and delays.
For SEO-critical pages, the safest approach is to ensure that important content and metadata are available in the initial HTML response whenever practical.
Check What Exists Without JavaScript
One useful audit is to disable JavaScript and inspect the resulting page.
Ask:
- Is the main content still present?
- Are important navigation links available?
- Is the page title present?
- Is the meta description present?
- Are canonical tags present?
- Can search engines discover important internal links?
Your critical SEO information should not depend entirely on a client-side JavaScript execution step.
Keep Metadata in the Initial Response
Avoid relying on client-side effects to inject important SEO metadata after the page has loaded.
Important elements such as:
<title>...</title>
<meta name="description" content="...">
<link rel="canonical" href="...">
should be generated as part of the server-rendered or statically generated HTML whenever possible.
This is especially important for frameworks that support both server and client components.
Use Real Internal Links
Internal navigation should use standard HTML links:
<a href="/services/web-development">
  Web Development
</a>
Avoid making important navigation dependent solely on:
<div onClick={...}>
or other JavaScript-only interaction patterns.
JavaScript-powered navigation can still be useful for application interfaces, but important crawlable relationships should be represented using normal hyperlinks.
4. Semantic Markup and Structured Data
Search engines need more than raw text to understand what a page represents.
Structured data helps describe the entities and relationships present on your website.
For example, a company website might contain:
Organization
   │
   ├── Service
   │
   ├── Article
   │     └── Author
   │
   └── BreadcrumbList
This gives search engines additional context about the relationships between your content.
Implement JSON-LD Schema
Use structured data appropriate to the actual content and entities on the page.
Depending on the website, this may include:
OrganizationWebSiteServiceArticleBreadcrumbListProductLocalBusiness
Do not add schema simply because it exists.
The structured data should accurately represent the visible content and purpose of the page.
Connect Related Entities
Where appropriate, structured data can establish relationships between entities.
For example:
Article
   ↓
Author
   ↓
Organization
or:
Organization
   ↓
Service
   ↓
Service Page
Using consistent entity identifiers and URLs can help search engines build a clearer understanding of your website.
Validate Structured Data
Before deploying structured data, validate production templates and check for:
- Missing required properties
- Invalid values
- Incorrect data types
- Missing author information
- Invalid dates
- Incorrect URLs
- Unsupported properties
Schema validation should become part of the development process rather than a one-time exercise.
5. Security, HTTP Status Codes, and Server Health
Technical SEO is also closely connected to basic infrastructure quality.
Search engines and users both benefit from a website that responds consistently, uses secure connections, and avoids unnecessary redirects or server errors.
Enforce HTTPS Consistently
Every public page should use HTTPS.
Configure HTTP-to-HTTPS redirects and ensure that internal links, canonical URLs, sitemaps, and resources consistently reference the HTTPS version.
For additional security, consider using HTTP Strict Transport Security (HSTS) where appropriate.
Maintain a Clean HTTP Status Profile
Regularly identify pages returning unexpected status codes.
Pay particular attention to:
404errors410responses500server errors- Incorrect
301redirects - Redirect chains
- Redirect loops
For example, avoid:
301 → 301 → 301 → 200
Prefer:
301 → 200
Internal links should point directly to the final destination instead of relying on multiple redirects.
Monitor Time to First Byte
Time to First Byte (TTFB) measures how quickly the server begins responding to a request.
For public-facing pages, keeping TTFB low is important for both user experience and overall performance.
Depending on the architecture, improvements can include:
- Edge caching
- Full-page caching
- Database query optimization
- Server-side caching
- CDN delivery
- Reducing unnecessary server-side processing
For many public pages, a TTFB below roughly 800 milliseconds is a useful performance target, although the appropriate target depends on the application and infrastructure.
Platforms such as Cloudflare and Vercel can provide edge caching and distributed delivery capabilities when configured appropriately.
Integrating Technical SEO Into Your Deployment Pipeline
Technical SEO should not be treated as a one-time project completed when a website launches.
Every deployment can introduce new problems.
A new feature can create layout shifts. A redesign can break canonical URLs. A CMS update can generate duplicate pages. A new JavaScript dependency can increase page weight. A routing change can create broken links.
That is why technical SEO should become part of your continuous quality assurance process.
Add SEO Checks to CI/CD
Where practical, automate checks for:
- Lighthouse performance
- Core Web Vitals regressions
- Broken internal links
- Sitemap validity
- Canonical tags
- Robots directives
- Structured data
- HTTP status codes
- Missing metadata
A simplified deployment workflow might look like:
Code Change
     ↓
Automated Tests
     ↓
SEO Validation
     ↓
Performance Checks
     ↓
Staging
     ↓
Crawl Test
     ↓
Production
This approach catches technical SEO regressions before they become indexing or ranking problems.
Technical SEO Is Part of Web Engineering
The strongest SEO foundations are built into the architecture rather than added after development is complete.
A search-friendly web platform should be:
- Easy to crawl
- Fast to render
- Stable on mobile
- Clear in its URL structure
- Accessible through semantic HTML
- Rich in accurate structured data
- Secure and reliable
- Continuously monitored
Content still matters. Keywords still matter. Search intent still matters.
But none of those efforts can reach their full potential if the underlying platform makes it difficult for search engines to discover, understand, and efficiently process your content.
Technical SEO is not separate from good engineering. For modern web platforms, it is part of good engineering.
Need a Technical SEO Audit?
Want to uncover crawlability issues, improve Core Web Vitals, fix indexing problems, or restructure your application for stronger organic and AI discovery?
Explore our technical SEO audit and engineering services to build a faster, more discoverable, and technically sound foundation for long-term search growth.